Marketplace›AI and automation›AI development and chatbots›Hardened, fully offline RAG search engine build and deployment on private server or hardware
Hardened, fully offline RAG search engine build and deployment on private server or hardware

Hardened, fully offline RAG search engine build and deployment on private server or hardware

AI development and chatbots · delivered in 5-14 days

What you receive

  • Pilot Node: configuration of an offline RAG search setup on 1 local workstation (macOS, Linux or Windows), reading standard text-based PDFs and linked to your existing Ollama installation, with 1 revision round, delivered in 5 days.
  • Hangar Service: a multi-user RAG deployment across your private network or dedicated hardware, with custom ingestion pipelines built for complex PDFs holding technical tables, schematics and figures, plus 2 revision rounds, delivered in 10 days.
  • Sovereign Vault: a fully air-gapped, enterprise-grade RAG build on isolated hardware, with advanced chunking tuned for specialist proprietary or technical files, 3 revision rounds, and 30 days of direct engineering support after launch.

Many document assistants push proprietary PDFs to external cloud servers. For anyone working with flight manuals, engineering schematics, legal files or otherwise restricted material, that transfer is a genuine security gap.

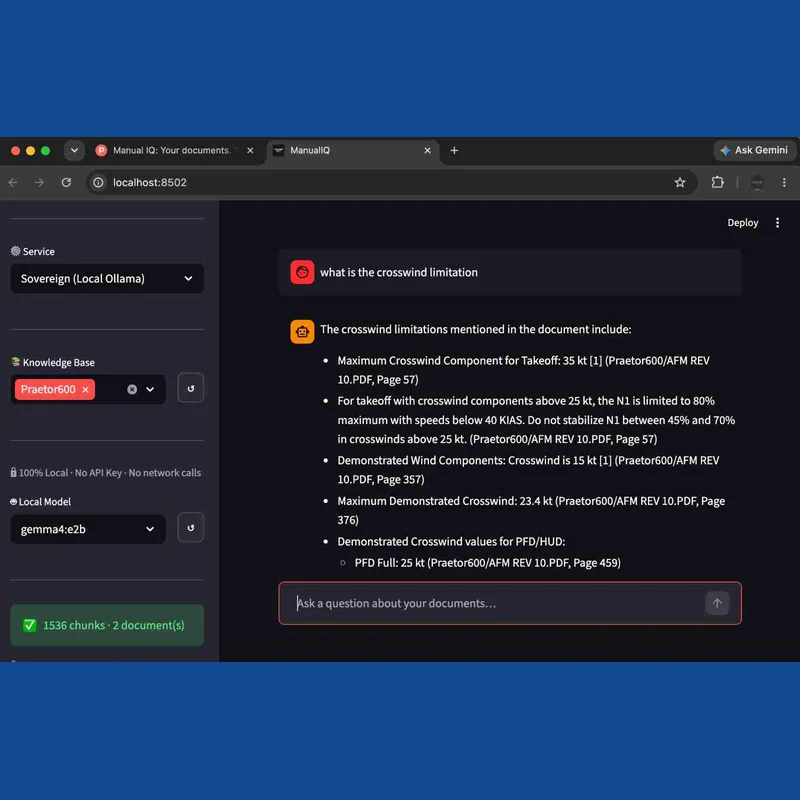
We install a hardened, local-first retrieval pipeline that operates entirely on your own hardware, built on Ollama and a local vector store. There are no cloud dependencies, no ongoing data subscriptions, and your documents stay under your own control at all times.

Core components

  • Local vector database setup: secure indexing of your document library on local SSD storage.
  • Ollama tuning: model selection and parameter adjustment matched to your hardware, whether macOS, Linux or Windows.
  • Technical parsing pipelines: ingestion built to extract tables, schematics and figures from complex files.
  • Offline query interface: a direct way to search your knowledge base without an active internet connection.

How we deliver it

  1. Assessment: we review your hardware and document formats to choose a suitable open-source model.
  2. Deployment: we install the vector store, embedding models and Ollama integration on your chosen machine or server.
  3. Ingestion: your files are parsed, chunked and embedded locally.
  4. Validation: we test accuracy, speed and hardware use to confirm the system runs stably and stays offline.

Packages at a glance

Pilot Node

  • Suits a single professional working on one machine.
  • Full offline RAG configuration on 1 workstation (macOS, Linux or Windows), connected to Ollama, with basic text PDF indexing and 1 revision.
  • Delivery: 5 days.

Hangar Service

  • Suits teams needing shared access on private infrastructure.
  • Multi-user deployment on your network or dedicated hardware, with pipelines tuned for technical PDFs containing schematics and tables, 2 revisions.
  • Delivery: 10 days.

Sovereign Vault

  • Suits organisations needing maximum isolation and security.
  • Fully air-gapped build on isolated hardware, custom chunking for specialised technical databases, 3 revisions, plus 30 days of direct engineering support.
  • Delivery: 14 days.

Why work with us

This work is carried out by our own engineering team. We do not resell software wrappers or subscription services. We build hardened systems for operators who need genuine data security and no cloud exposure.

What happens after you buy

Your order opens its own thread here the moment it is paid, and everything about that order - questions, changes and the final report - happens in it.
Questions people ask

How do I know my documents are actually offline and secure?

Your files remain on your own hardware throughout. The embedding models, vector database and language model all run locally, with no external cloud calls involved. You can even disconnect your machine from the internet while using the system to confirm there is no outgoing network traffic.

What kind of hardware do I need to run this local RAG engine?

The Pilot Node package runs comfortably on a standard modern computer with 16GB of RAM. For heavier technical files and multi-user setups, we suggest dedicated hardware such as an Apple Silicon machine with 32GB or more of unified memory, or a graphics card offering plenty of video memory, so that queries return quickly.

How does this differ from cloud assistants like ChatGPT or custom GPTs?

Cloud assistants send your files to their own servers, which is a real concern for proprietary material, and they typically charge ongoing monthly fees. Our local RAG build is a one-off setup carried out entirely on your own equipment, giving you full control over your data without recurring costs.

People also buy

AI development and chatbots

AI agent and custom LLM integration for business workflows

We build and integrate AI agents and custom LLMs into your workflows, automating support, lead handling, data extraction and content tasks so your team can focus on higher-value work.

$375.99 - $1,874.99PACKAGES FROM 3-8 days
AI development and chatbots

AI chatbot training and response optimization

PBN.LTD reviews and refines your existing AI chatbot, improving prompts, FAQ handling and conversation flow so it responds more naturally and supports customers better.

$12.99 - $118.99PACKAGES FROM 1-5 days
AI development and chatbots

AI voice receptionist for your business

A custom-built AI voice receptionist that answers calls around the clock, books appointments and logs customer details automatically for clinics, salons and service businesses.

$62.99 - $437.99PACKAGES FROM 3-7 days